How Search Engine Works: Diagram
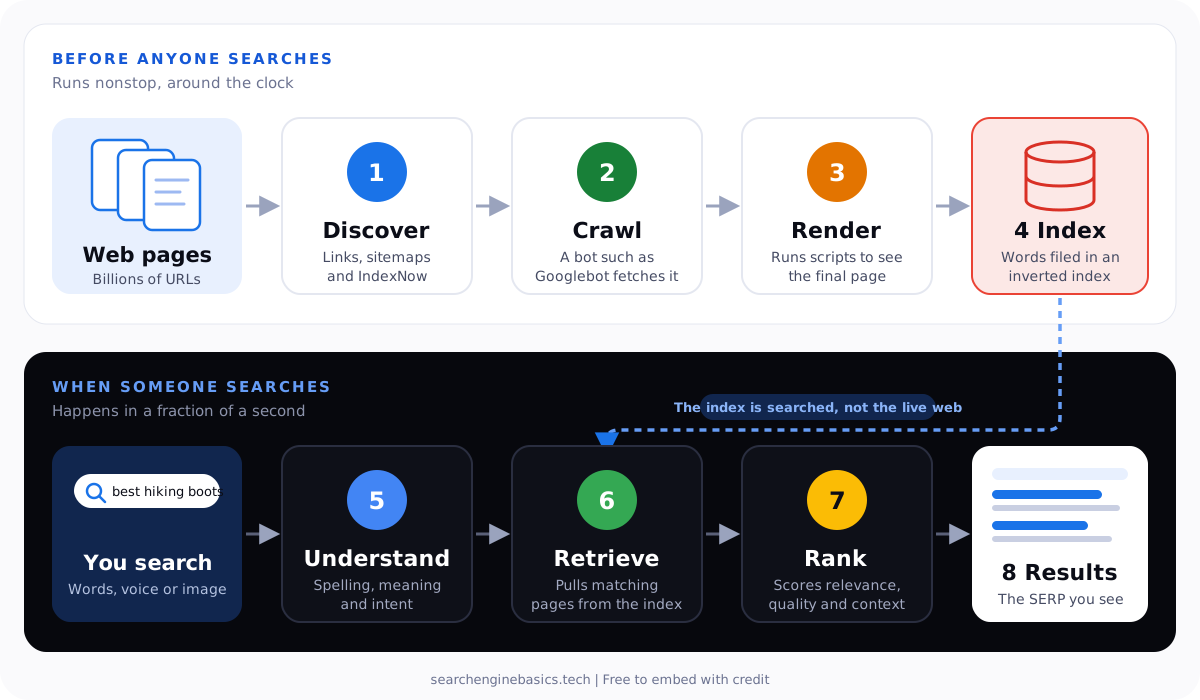
This how search engine works diagram shows the whole system on one page, from a bot finding a URL to a ranked list of results. The top lane runs nonstop before anyone searches, while the bottom lane happens in the second after you press Enter.
A search engine works in two lanes. Before anyone searches, it discovers, crawls, renders and indexes pages. When you search, it understands your query, retrieves matching pages from the index, ranks them, then shows the results page.
 Written by Usman AliGrowth and SEO specialist · 7 years in SEO
The diagram
The Search Engine Diagram
Read it left to right, top lane first. The dashed line marks the most important idea: results come from the index, never from the live web.
Swipe sideways to see the full diagram
Step by step
Each Stage in One Sentence
Use this table as a legend for the diagram. Every row links to the guide that explains that stage in depth.
| Stage | What happens | Learn more |
|---|---|---|
| 1. Discover | The engine learns a URL exists through links, an XML sitemap or an IndexNow ping. | Crawling guide |
| 2. Crawl | A bot such as Googlebot requests the page, then saves what the server sends back. | Web crawlers |
| 3. Render | The engine runs the page’s scripts so it sees the same content a visitor would. | Five-stage guide |
| 4. Index | The text is split into words, then filed in an inverted index that points back to the page. | Indexing guide |
| 5. Understand | The engine fixes spelling, adds synonyms, then works out what the searcher really wants. | Components |
| 6. Retrieve | It pulls every page from the index that could match, often thousands of candidates. | Components |
| 7. Rank | Ranking systems score each candidate for relevance, quality, freshness or context. | Ranking guide |
| 8. Results | The best pages appear on the SERP, sometimes beside snippets, maps or an AI Overview. | What is a SERP |
The big idea
Why the Diagram Has Two Lanes
Splitting the work in two is what makes search fast. The slow jobs happen ahead of time, so the fast jobs have something ready to search.
Building the index
Crawlers work around the clock, visiting new pages while revisiting old ones. Google describes crawling billions of pages with a huge set of computers, which no single search could ever wait for.
Answering the query
When you search, the engine only has to look up your words in its index, then sort the matches. That shortcut is why results appear in a fraction of a second.
Engineers often draw a far busier search engine architecture diagram, full of data centers, caches and load balancers. Underneath, it still follows this same search engine workflow. For the full story behind every box, read our guide to how search engines work, or see what each part does in the components of a search engine.
Free to share
Embed This Diagram
Teachers, bloggers or course creators may use the diagram for free. Please keep the credit link so readers can find the full explanation.
FAQ
Questions About the Diagram
Can I use this diagram on my site?
Yes. You may embed or print it for free, including in lessons or slides. The only condition is a visible credit link to searchenginebasics.tech.
Is this how Google works?
Yes, in simplified form. Google describes three stages: crawling, indexing and serving results. This diagram splits those three into eight smaller steps so each one is easier to picture.
What are the main parts of a search engine?
The core parts are a crawler, an indexer with its index, a query processor and a ranking system. A user interface then displays the results page.
Why does the diagram start with discovery?
A crawler can only visit a URL it already knows about. Discovery through links or sitemaps is the step that puts a new page on the crawler’s list.